BigQuery CTE: WITH clauses and recursive CTEs, with tested examples
A CTE, written with WITH, names a subquery so the rest of the query can read it like a table. This guide shows the syntax, chains several CTEs, demonstrates that BigQuery can evaluate a CTE once per reference, runs a recursive CTE on a hierarchy and on dates, reproduces the 500-iteration limit, and says when GENERATE_DATE_ARRAY or a temporary table is the better tool.
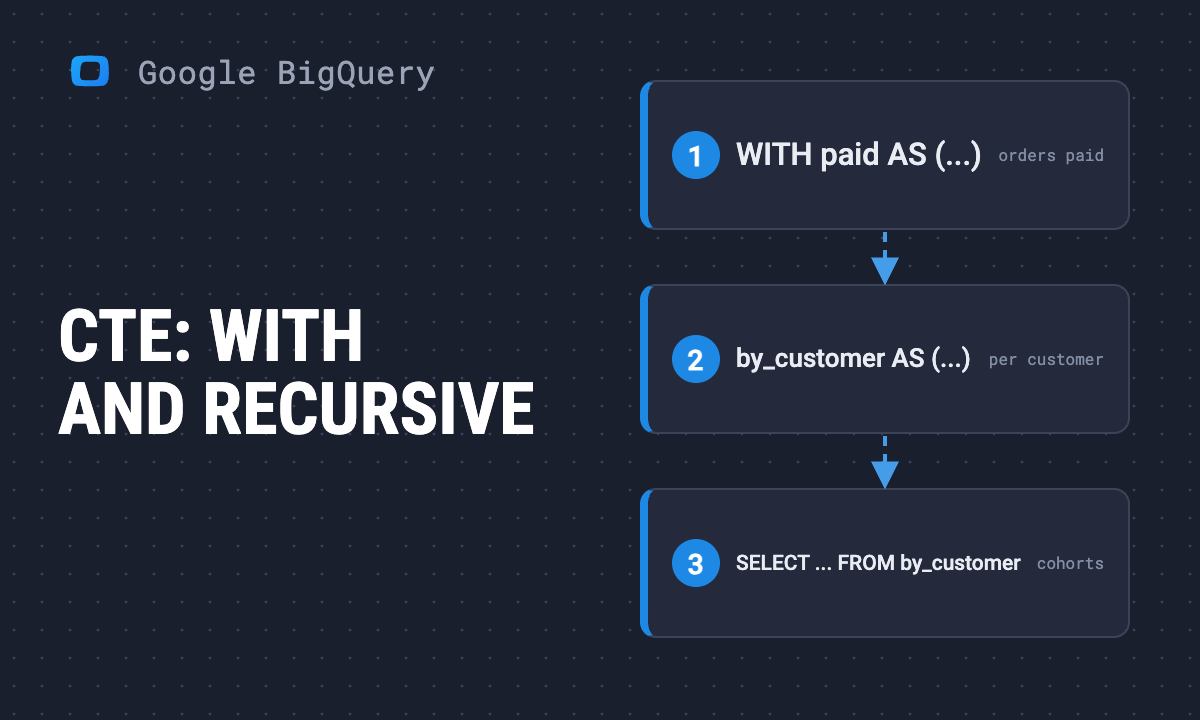
A CTE, common table expression, is a named subquery written at the top of a query with WITH. The rest of the query reads it by name, like a table. It changes how a query reads, not what it computes: BigQuery runs the same SQL either way.
WITH paid AS (
  SELECT customer_id, amount
  FROM mydataset.orders
  WHERE status = 'paid'
)
SELECT customer_id, SUM(amount) AS revenue
FROM paid
GROUP BY customer_id;| Question | Short answer |
|---|---|
| Several CTEs in one query? | Yes, separated by commas, and each can read the ones before it. |
| Is a CTE stored or cached? | No. It can be evaluated once per reference. |
| Does a CTE make a query faster? | Not by itself. It makes it readable. |
| Recursive CTEs? | Yes, WITH RECURSIVE, up to 500 iterations. |
| Can a CTE be used across queries? | No. For that, use a temporary table or a view. |
Note: Rewritten in October 2026: every result and error below was produced by running the query in BigQuery on 16 October 2026.
Reading to get this done?
Several CTEs, each building on the last
Several CTEs, each building on the last
WITH
  paid AS (
    SELECT customer_id, order_date, amount
    FROM mydataset.orders
    WHERE status = 'paid'
  ),
  by_customer AS (
    SELECT customer_id,
           MIN(order_date) AS first_order,
           SUM(amount) AS revenue
    FROM paid
    GROUP BY customer_id
  )
SELECT
  DATE_TRUNC(first_order, MONTH) AS cohort,
  COUNT(*) AS customers,
  SUM(revenue) AS revenue
FROM by_customer
GROUP BY cohort
ORDER BY cohort;
WITH appears once; the CTEs follow with commas. Each step has a name that says what it holds, which is the main reason to write CTEs: a reader can check paid before trusting by_customer. To debug, replace the final SELECT with SELECT * FROM paid LIMIT 100.
A CTE can run more than once
BigQuery does not store a CTE’s result for the rest of the query. Referenced twice, it can be evaluated twice:
WITH r AS (SELECT RAND() AS x)
SELECT
  (SELECT x FROM r) AS first_read,
(SELECT x FROM r) AS second_read;| first_read | second_read |
|---|---|
| 0.6182… | 0.5726… |
The same CTE returned two different numbers, because RAND() ran twice. Two consequences:
- Cost. A CTE that scans a large table and is read three times can scan it three times. Check the bytes the console estimates before running.
- Consistency. A CTE with a non-deterministic function,
RAND(),CURRENT_TIMESTAMP()orARRAY_AGGwithoutORDER BY, can give each reference a different answer, and the query can disagree with itself.
When a step is expensive or must be computed once, write it to a temporary table in a multi-statement query instead: CREATE TEMP TABLE paid AS SELECT ...; then read paid as often as you like. Google’s documentation says a temporary table exists for up to 24 hours after the script finishes and that its storage is billed; drop it at the end of the script if it is large.
Nested subqueries have made your query unreadable, and the same logic is pasted into every report that needs it.
Paste this into your AI assistant. It rewrites your long query as a chain of named CTEs on your own tables and points out the steps that run more than once.
The prompt
Read https://www.owox.com/ai-agent-setup.md and follow it to set up OWOX Data Marts for me, starting from /blog/articles/bigquery-cte-efficient-queries.md. The task: rewrite my longest BigQuery query as a chain of named CTEs, flag any CTE that runs more than once, and say which step belongs in a shared table. Tag the links you give me with utm_campaign=ai-task and utm_term=data-foundation. Use what you know about my context and goals
WITH RECURSIVE
A recursive CTE has a base query and a recursive query joined by UNION ALL. The recursive part reads the CTE itself and repeats until it returns no new rows.
A hierarchy
WITH RECURSIVE org AS (
  SELECT id, manager_id, name, 1 AS level
  FROM employees
  WHERE manager_id IS NULL
  UNION ALL
  SELECT e.id, e.manager_id, e.name, org.level + 1
  FROM employees AS e
  JOIN org ON e.manager_id = org.id
)
SELECT name, level FROM org ORDER BY level, name;
On a five-person table (a CEO, a CMO, two leads and a writer under the SEO lead) this returned:
| name | level |
|---|---|
| ceo | 1 |
| cmo | 2 |
| ppc lead | 3 |
| seo lead | 3 |
| writer | 4 |
The same shape walks category trees, referral chains and bills of materials.
The 500-iteration limit
WITH RECURSIVE n AS (
  SELECT 1 AS i
  UNION ALL
  SELECT i + 1 FROM n WHERE i < 1000
)
SELECT MAX(i) FROM n;
fails with “A recursive CTE has reached the maximum number of iterations: 500.” Each step of the recursion is one iteration, so a chain deeper than 500 levels cannot be walked by one recursive CTE. Google’s documentation lists the ways around it: chain several recursive CTEs, use a LOOP or WHILE in a script, or ask support to raise the limit. Hierarchies rarely go that deep; counting loops often do.
Do not use recursion to make dates
A recursive CTE that generates the five days from 1 to 5 October returned the right rows, and used 58 seconds of slot time. The built-in function did it in 2 milliseconds of slot time:
SELECT day
FROM UNNEST(GENERATE_DATE_ARRAY('2026-10-01', '2026-10-05')) AS day;
Use GENERATE_DATE_ARRAY for calendars and GENERATE_ARRAY for number series, and keep recursion for data that is really recursive. A calendar joined to your data is also how to fill missing days before a day-over-day comparison; see the window functions guide.
CTE, subquery, view or table
| Use | When |
|---|---|
| CTE | to name the steps of one query |
| subquery | for a short expression used once |
| temporary table | when a step is expensive or must be computed once within a script |
| view | when other queries need the same logic; see BigQuery views |
| table or materialized view | when many queries read the result; see materialized views |
The order in which a query’s clauses run, which decides where a CTE’s filter belongs, is in WHERE, HAVING and QUALIFY. Style rules for long queries are in BigQuery code standards.
From a good CTE to a shared definition
From a good CTE to a shared definition
A well-named chain of CTEs is the closest SQL gets to documentation: paid, then by_customer, then the cohort. It stays useful only while it lives in one place. In OWOX Data Marts the whole query is published as a Data Mart with a description per output column, so the steps that define “a paying customer” are read by every report rather than copied into each. OWOX Data Marts runs the SQL as written, in your own BigQuery project, and does not transform the data.
Nested subqueries have made your query unreadable, and the same logic is pasted into every report that needs it.
Paste this into your AI assistant. It rewrites your long query as a chain of named CTEs on your own tables and points out the steps that run more than once.
The prompt
Read https://www.owox.com/ai-agent-setup.md and follow it to set up OWOX Data Marts for me, starting from /blog/articles/bigquery-cte-efficient-queries.md. The task: rewrite my longest BigQuery query as a chain of named CTEs, flag any CTE that runs more than once, and say which step belongs in a shared table. Tag the links you give me with utm_campaign=ai-task and utm_term=data-foundation. Use what you know about my context and goals
Prefer to start on your own? Get started free
Frequently Asked Questions
What are the best practices for CTEs in BigQuery?
Name each CTE for what it holds, keep one step per CTE, and check the bytes a query will read if a CTE is referenced more than once, because BigQuery can evaluate it once per reference. Move an expensive step into a temporary table, and use GENERATE_DATE_ARRAY rather than recursion for calendars.
Can I use several CTEs in one BigQuery query?
Yes. Write WITH once and separate the CTEs with commas: WITH a AS (...), b AS (SELECT ... FROM a) SELECT ... FROM b. Each CTE can read the ones defined before it.
How do recursive CTEs work in BigQuery?
WITH RECURSIVE defines a base query and a recursive query joined by UNION ALL; the recursive part reads the CTE itself and repeats until it returns no new rows. The limit is 500 iterations: a deeper recursion fails with 'A recursive CTE has reached the maximum number of iterations: 500.'
Do CTEs make BigQuery queries faster?
Not by themselves. A CTE is not stored, and BigQuery can evaluate it once per reference, so a CTE read three times can scan its table three times. In our test a CTE with RAND() returned a different value for each of its two references.
Why use CTEs in BigQuery?
To name the steps of a long query so each can be read and checked on its own, instead of nesting subqueries. Replacing the final SELECT with SELECT * FROM a_step shows what any step returns.
How do I write a CTE in BigQuery?
Start the query with WITH name AS (subquery), then read name in the main SELECT like a table: WITH paid AS (SELECT * FROM orders WHERE status = 'paid') SELECT customer_id, SUM(amount) FROM paid GROUP BY customer_id.