QUERY with UNIQUE in Google Sheets: how to return distinct rows
The QUERY function has no DISTINCT keyword. Wrapping it in UNIQUE returns each row of the result once; a group by clause does the same when you also need totals. This guide shows both, the Col1 notation for UNIQUE inside QUERY, and the mistakes that make the formulas fail.
The QUERY function in Google Sheets has no DISTINCT keyword, so a query cannot remove duplicate rows by itself. The fix is to wrap it in UNIQUE: =UNIQUE(QUERY(range, “select B, C”)) runs the query first and then returns each resulting row once.
This guide shows that combination in three situations, the reverse order (UNIQUE inside QUERY), the group by alternative when you also need totals, and the mistakes that make either formula fail.
Note: Originally published in January 2024. Fully updated in October 2026: the error section was rewritten (two of its “corrections” were themselves wrong), and the group by alternative and the UNIQUE-inside-QUERY pattern were added.
The two functions in brief
QUERY
=QUERY(data, query, [headers])
- data: the range to query.
- query: the instruction, in quotes: which columns to return, which rows to keep, how to sort or group.
- headers (optional): the number of header rows at the top of the data. If omitted, Google Sheets guesses.
💡 Everything else QUERY can do is in our guide to QUERY in Google Sheets.
UNIQUE
=UNIQUE(range, [by_column], [exactly_once])
UNIQUE returns the rows of a range with the duplicates left out. It compares whole rows: with two columns, a row is a duplicate only if both cells match.
Distinct values and unique values
The two words are often used as if they meant the same. They do not:
- Distinct values: every value once, however often it appears. This is what UNIQUE returns by default.
- Unique values: only the values that appear exactly once. UNIQUE returns these when the third argument, exactly_once, is TRUE.
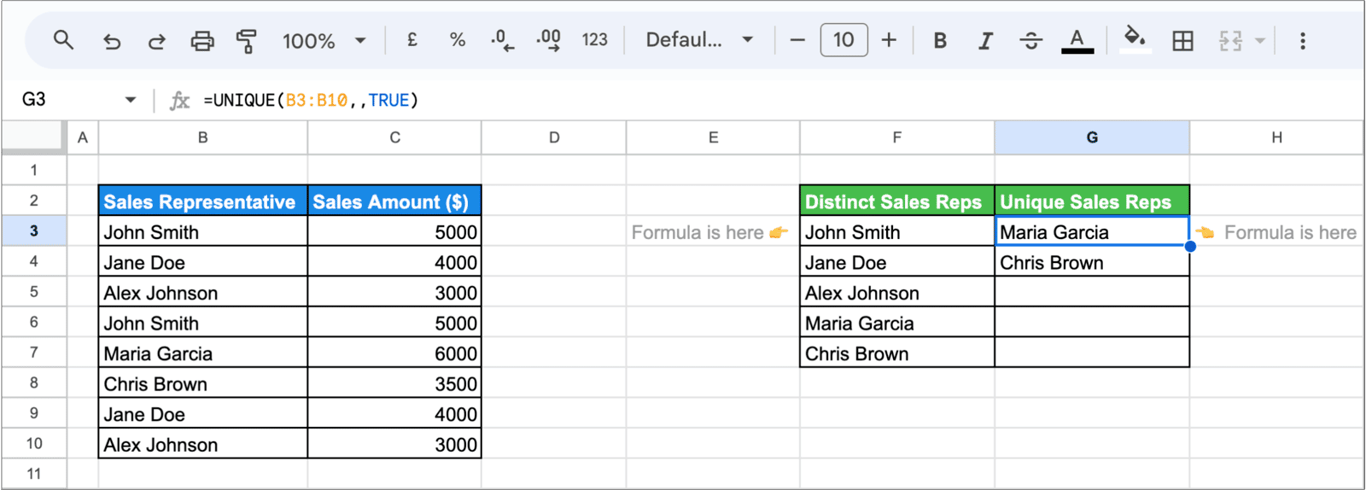
For a list of sales representatives, the default lists everyone once, and =UNIQUE(B3:B10,,TRUE) lists only the representatives with a single sale:
💡 More on the function in our guide to UNIQUE in Google Sheets.
Distinct rows from a QUERY: three examples
Distinct rows from a QUERY: three examples
The examples use a table of sales with the representative in column B, the region in column C and the amount in column D.
1. Distinct rows of the whole table
=UNIQUE(QUERY(B3:D10, "SELECT B, C, D"))
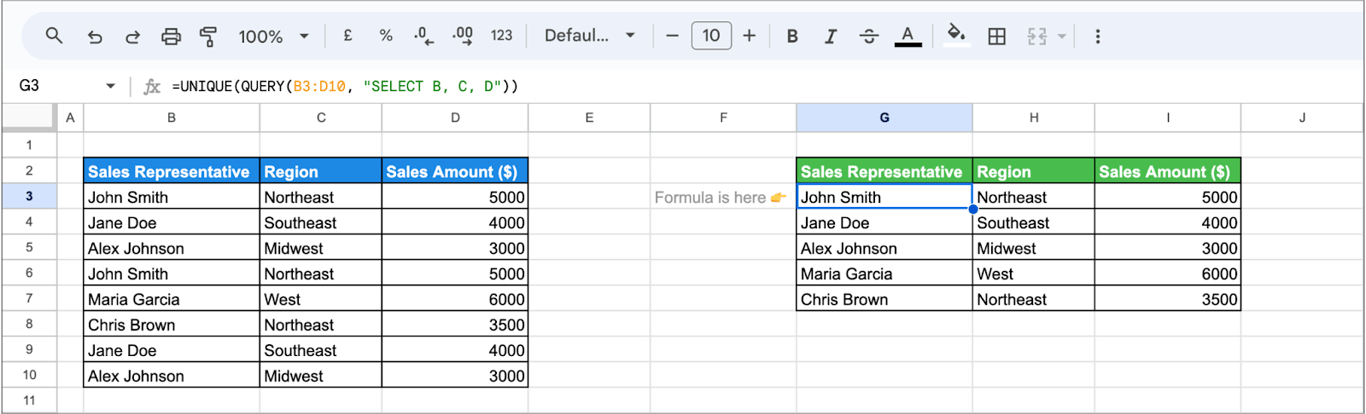
The query returns all three columns, and UNIQUE drops the rows where representative, region and amount are all the same as in an earlier row. Two sales by the same person for different amounts both stay.
2. Distinct combinations of some columns
Select fewer columns and the comparison gets coarser. To list each representative and region pair once:
=UNIQUE(QUERY(B3:D10, "SELECT B, C"))
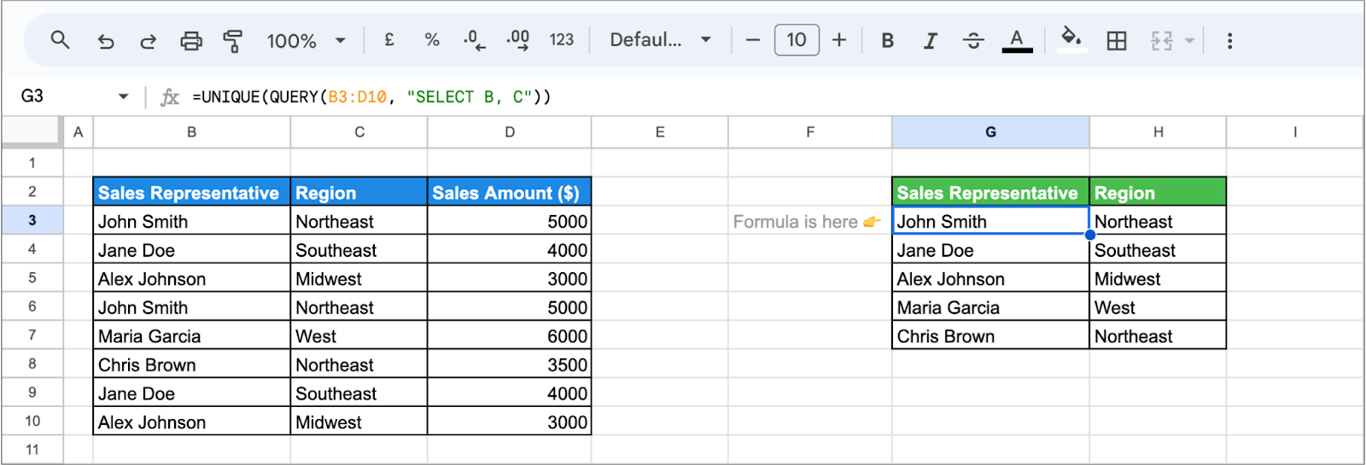
Select a single column, “SELECT C”, and you get the list of distinct regions.
3. Distinct rows that meet a condition
A where clause filters before the duplicates are removed. To list the distinct rows for two representatives only:
=UNIQUE(QUERY(B3:C10, "SELECT B, C WHERE B='John Smith' OR B='Jane Doe'"))
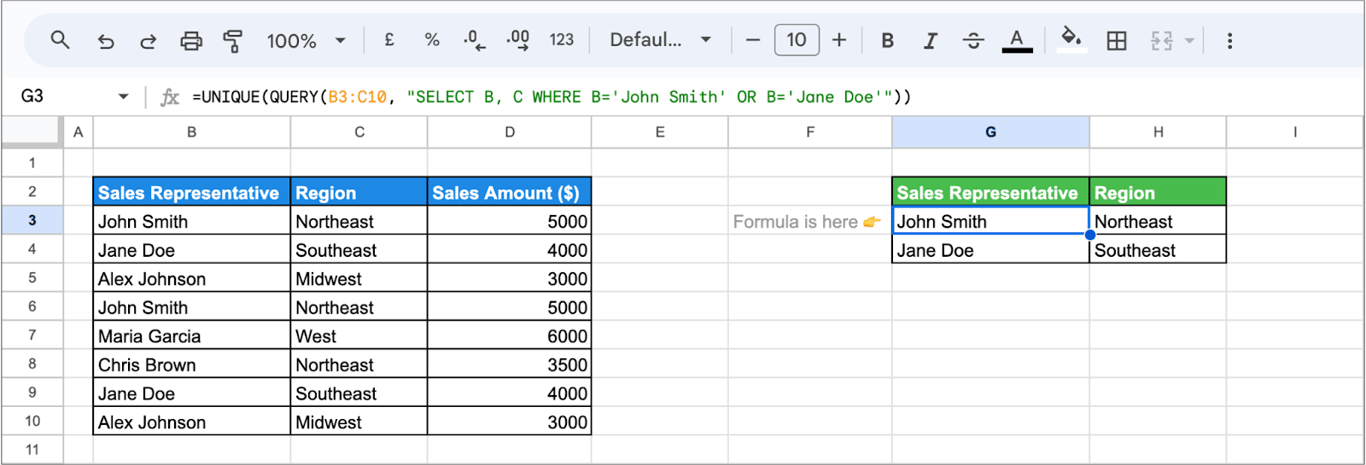
Text values in the query are written in single quotes, because the whole query is already inside double quotes.
OWOX Data Marts
See your first report built in real time. 15 minutes.
- Connect your data warehouse
- Pick your metrics
- Get a live Google Sheets report
In the time it takes to write a ticket. Then imagine never writing that ticket again.
Book a DemoWe'll use your actual use case
UNIQUE inside QUERY
The order can be reversed: remove the duplicates first, then query the result.
=QUERY(UNIQUE(B3:D10), "select Col1, Col3 where Col3 > 4000 order by Col3 desc")
One thing changes. UNIQUE returns an array, not a range of the sheet, so the query can no longer use column letters. Columns are called Col1, Col2, Col3, counted from the left of the array.
Use this order when the condition should apply to the deduplicated data, or when you want the query to sort the final result.
When you also need totals: group by
When you also need totals: group by
If the goal is one row per value with a number next to it, you do not need UNIQUE at all. A group by clause returns each value once and aggregates the rest:
=QUERY(B3:D10, "select B, sum(D) group by B")
This returns each representative once with the total of their sales. count(), avg(), max() and min() work the same way. Every column in the select must either be in the group by or be inside an aggregate function.
To count the distinct values a query returns, wrap the combination in COUNTA: =COUNTA(UNIQUE(QUERY(B3:D10, "select C"))).
Why the formula fails or returns too many rows
Why the formula fails or returns too many rows
Column letters in the query
Column letters in a query must be upper case and must be columns of the data range: with B3:D10 as the data, you can select B, C and D, not A or E. When the data is an array, such as the output of UNIQUE or two ranges in curly braces, use Col1, Col2 instead of letters. Mixing the two styles returns a #VALUE! error with “Unable to parse query string”.
Quotes
The query is wrapped in double quotes, so text values inside it take single quotes: where B = 'John Smith'. Column references take no quotes at all. Written as ‘Col1’, a column reference becomes a piece of text and no longer refers to the column.
The header row appears in the result
If the header shows up as a data row, or a data row is treated as a header, set the third argument of QUERY: 1 when the range starts with one header row, 0 when it has none.
Values that look identical are returned twice
UNIQUE compares exactly. “Northeast” and “northeast”, or “Northeast” with a trailing space, are different values. Clean the column with TRIM and one of the case functions before deduplicating, or fix the entries at the source.
A column loses some of its values
QUERY expects one data type per column. In a column that mixes numbers and text, it keeps the majority type and treats the rest as empty. Convert the column to one type first; TO_TEXT turns everything into text.
The formula is slow
On a large range, filter first and deduplicate second: UNIQUE(QUERY(…)) with a where clause hands UNIQUE fewer rows to compare. Open-ended ranges such as B3:D make both functions scan every row of the sheet, so close the range when you can.
An alternative without formulas: a pivot table
An alternative without formulas: a pivot table
A pivot table (Insert → Pivot table) lists each value of a field once when you add the field to Rows, and can add a sum, an average or a count next to it. It suits people who prefer to build the summary by clicking.
Related Google Sheets functions
Related Google Sheets functions
Functions that are often used next to QUERY and UNIQUE, each with its own guide:
- ARRAYFORMULA: Applies a formula to a whole column or range at once.
- VLOOKUP: Searches the first column of a range and returns a value from the same row. See also VLOOKUP combined with IF.
- HLOOKUP: The same lookup for data laid out in rows.
- XLOOKUP: A more flexible lookup that can return values from any direction.
- IMPORTXML, IMPORTHTML and IMPORTFEED: Import data from web pages and feeds.
- CONCATENATE: Joins several pieces of text into one string.
- QUERY date filtering: Filters rows by a date or a date range inside a QUERY formula.
- QUERY vs VLOOKUP: Compares the two functions and shows when each is the better choice.
- Data validation: Restricts what can be entered in a cell with rules and drop-down lists.
Deduplicating in the sheet hides the question of why there are duplicates
Deduplicating in the sheet hides the question of why there are duplicates
UNIQUE(QUERY(…)) gives you a clean list every time the sheet recalculates. It does not tell you why the rows were duplicated: a join that matched one order to two campaigns, an export appended to last week’s export, a customer entered twice in the CRM. If the duplicates carry numbers, the totals elsewhere in the workbook may already include them.
The OWOX Data Marts extension for Google Sheets covers that half. A data analyst publishes a data mart (a table or an SQL query in your data warehouse) and makes it available for reports. In Sheets you open the extension, pick the data mart, tick the columns you want and run it. The rows land in a tab, ready for your formulas.
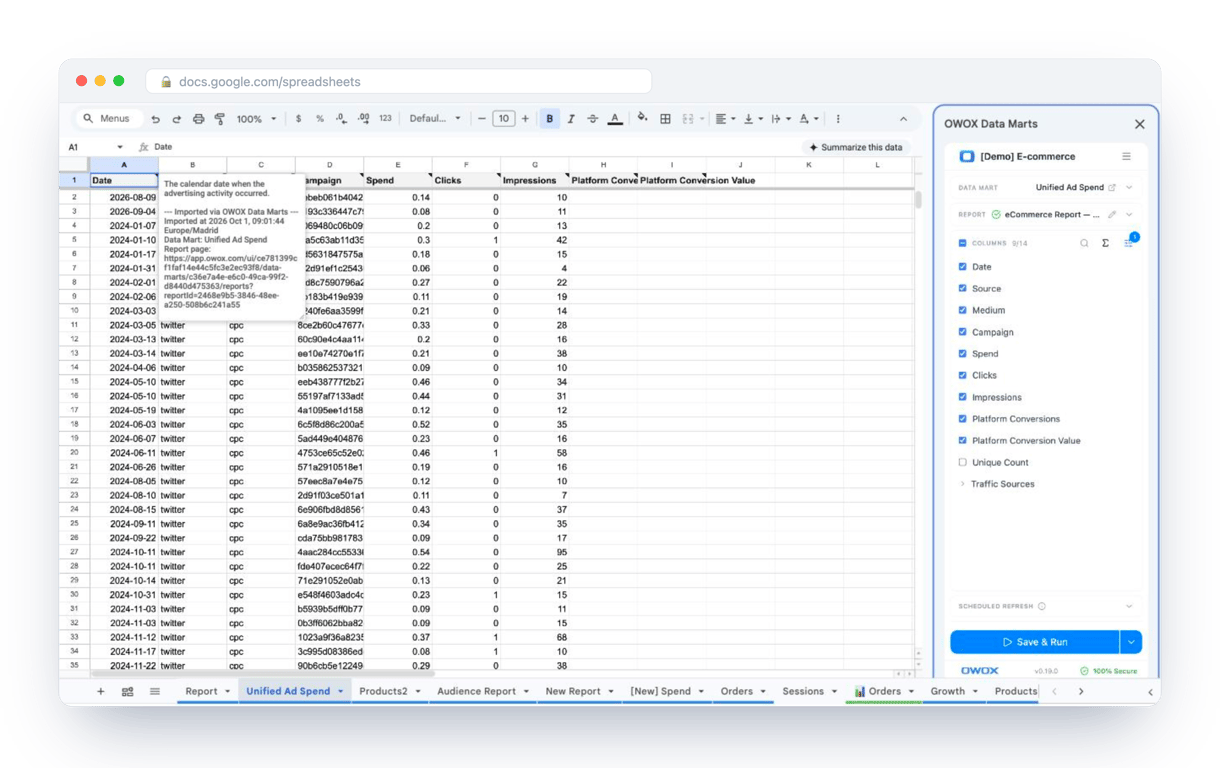
What changes for the person who maintains the sheet:
- Refresh replaces re-export. Refresh current report in the extension menu re-runs the same pull, and a scheduled refresh keeps the tab current without anyone touching it.
- The source is written on the sheet. The header cell of an imported tab carries a note with the data mart it came from, the time of the import and a link to the report.
- No SQL and no warehouse access needed. The analyst decides which data marts and columns are available. You choose from that list.
The extension does not write or change the analyst’s SQL. Whether a row appears once is decided there, in a query that can be read and checked, and QUERY and UNIQUE in the sheet are left to shape the result for the report. The extension comes with the OWOX Cloud plans of OWOX Data Marts; spreadsheet reporting describes both ways data reaches a sheet.
Turn your data into decisions.
Governed data marts give you the clean foundation ML needs to actually work.
- No AI hallucinations
- Analyst-governed definitions
- Every number traces to SQL
Frequently Asked Questions
What common issues might I encounter when using QUERY and UNIQUE together?
The usual ones: column letters written in lower case or outside the data range, column letters used where the data is an array (use Col1, Col2 instead), text values without single quotes, and a column that mixes numbers and text, in which QUERY treats the minority type as empty.
What is the syntax for using QUERY to display unique rows for a single column?
To display unique rows for a single column using QUERY, use the syntax: =UNIQUE(QUERY(A1:B16, "SELECT A WHERE A is not null")).
What function counts unique values in Google Sheets?
The COUNTUNIQUE function in Google Sheets counts the number of unique values in a range. Use the following formula: =COUNTUNIQUE(range).
How can I troubleshoot performance issues when using QUERY and UNIQUE on large datasets?
To troubleshoot performance, filter data with QUERY first to reduce dataset size and avoid complex calculations. Additionally, optimize formulas and minimize unnecessary array formulas.
Is there a UNIQUE function in Google Sheets?
Yes, Google Sheets has a UNIQUE function that extracts unique and distinct values from a range. The basic formula is: =UNIQUE(range).
What are some best practices for using QUERY and UNIQUE functions together?
Filter first and deduplicate second: UNIQUE(QUERY(range, "select ... where ...")). Use upper-case column letters for a range and Col1, Col2 for an array, keep one data type per column, and use group by instead of UNIQUE when you need a total next to each distinct value.
How do I handle multiple columns when displaying unique rows?
When handling multiple columns, include all desired columns in the SELECT statement within the QUERY function.
Can the QUERY function display only unique rows?
The QUERY function can display only unique rows by combining it with the UNIQUE function as follows: =UNIQUE(QUERY(data, query))